Agent Sessions
Session-Bench
Session-Bench measures whether coding-agent harnesses preserve a useful, inspectable, and portable record of their work — the session files they write to disk. SWE-bench measures whether the agent completed the work; Session-Bench measures what the harness preserved after the work was done. Twenty scored pass/fail gates across five areas, each backed by a measurement, a fixture, or a monitoring-ledger entry. No partial credit: a gate is pass, fail, or explicitly not run — never averaged.
Leaderboard
| # | Harness | Version | Format | Signal | Complete | Stable | Open | Tooling | Cleared |
|---|---|---|---|---|---|---|---|---|---|
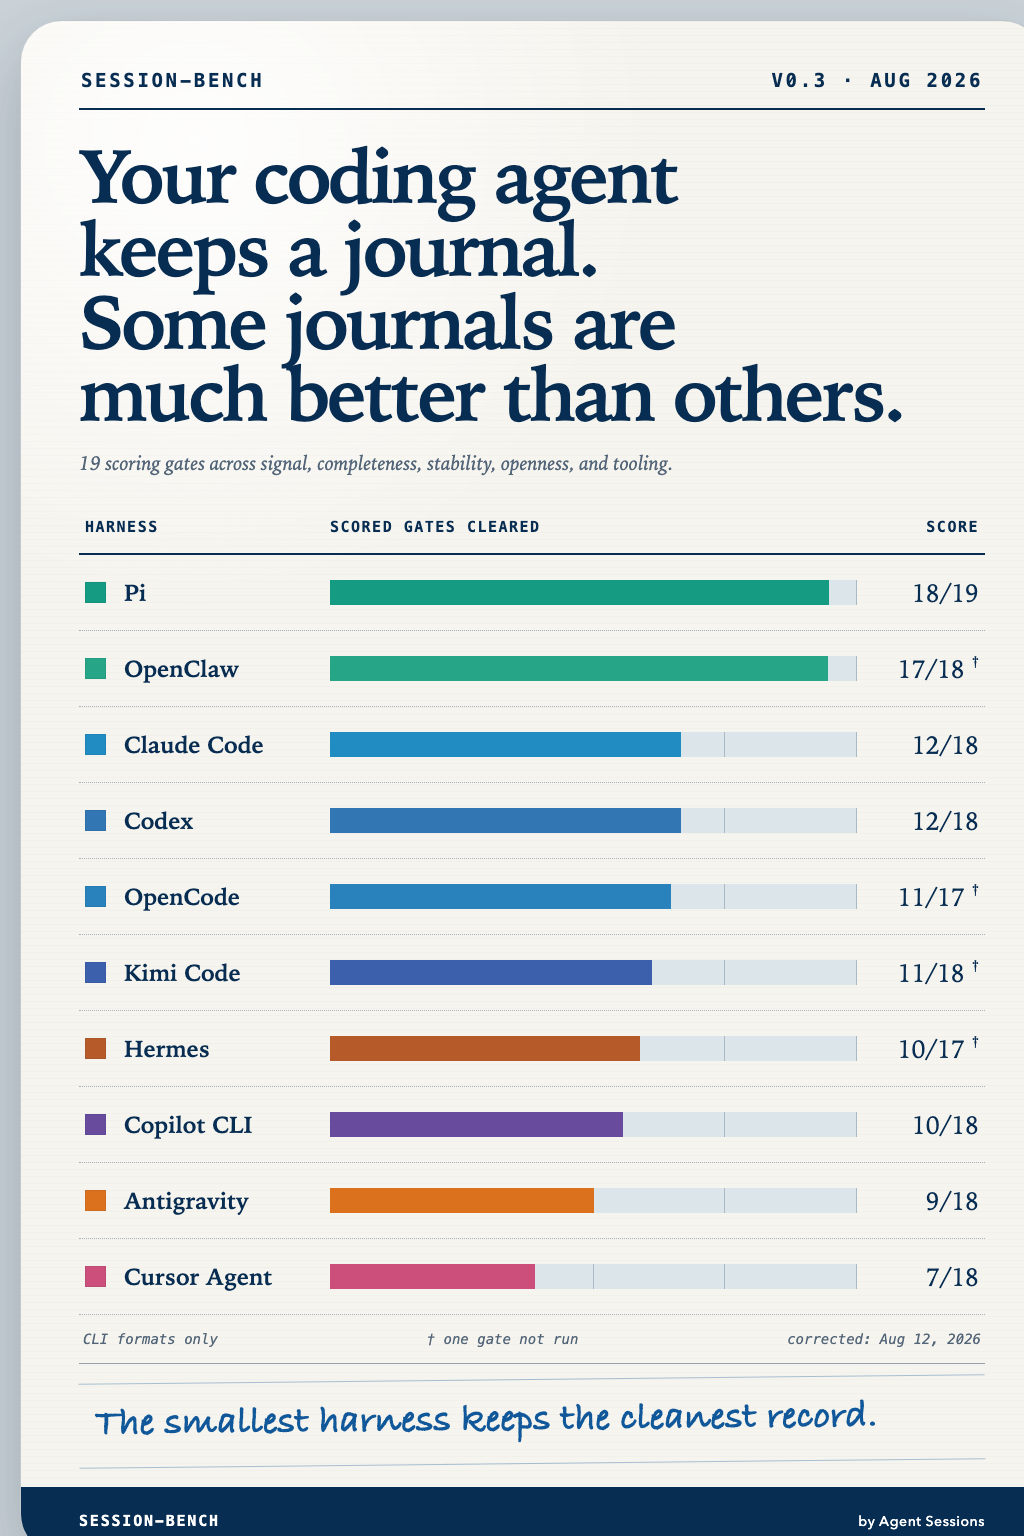
| 1† | Pi | 0.83.0 | Flat parent-linked JSONL | 3/3 | 7/7 | 3/3 | 4/4 | 1/2 | 18 / 19 (1 not run) |
| 2† | OpenClaw | 2026.6.11 | Flat parent-linked JSONL | 2/2 | 6/7 | 3/3 | 4/4 | 2/2 | 17 / 18 (2 not run) |
| 3† | Claude Code | 2.1.220 | Nested-envelope JSONL | 1/3 | 5/7 | 1/2 | 3/4 | 2/2 | 12 / 18 (1 not run) |
| 3† | Codex | 0.146.0 | Nested-envelope JSONL | 1/3 | 6/7 | 1/2 | 3/4 | 1/2 | 12 / 18 (1 not run) |
| 5† | Kimi Code | 0.31.1 | Wire-op journal (JSONL) | 0/3 | 6/7 | 2/2 | 3/4 | 0/2 | 11 / 18 (2 not run) |
| 5† | OpenCode | 1.18.11 | SQLite (session/message/part rows) | 2/3 | 6/7 | 0/2 | 1/4 | 2/2 | 11 / 18 (1 not run) |
| 7† | Hermes | 0.17.0 | SQLite ledger + FTS | 1/2 | 5/7 | 0/2 | 2/4 | 2/2 | 10 / 17 (2 not run) |
| 8† | Copilot CLI | 1.0.77 | Nested-envelope JSONL (event-sourced) | 1/3 | 5/7 | 0/2 | 3/4 | 1/2 | 10 / 18 (1 not run) |
| 9† | Antigravity | 1.1.1 | Step-typed JSONL | 3/3 | 3/7 | 0/2 | 2/4 | 1/2 | 9 / 18 (1 not run) |
| 10† | Cursor Agent | 2026.7.20 | Flat JSONL + binary metadata DB | 3/3 | 1/7 | 1/2 | 1/4 | 1/2 | 7 / 18 (1 not run) |
Ranking is by fraction of scored gates cleared; ties share a rank. A gate whose measurement could not be taken for a harness is marked not run and drops out of that harness's denominator — an authentication failure is not evidence about a format, and an observation window too short to judge stability (Kimi, onboarded 2026-07-25) is not evidence of stability. S4 is likewise not run wherever no collapse rule has been shown final-state-lossless for an entire source and measured on the corpus: absence of a qualifying rule is not leanness, and the one S4 fail measured so far is the largest waste number in the bench. Ranks marked † are provisional: hover for the best/worst range pending the missing measurement. Every gate carries equal weight within the composite; the per-area columns are there so you can re-weight by eye. One gate (crash tolerance) is defined but unscored pending a real cross-harness truncation experiment.
View or download the Session-Bench v0.3 poster (historical — the rubric is now v0.4 with twenty gates)
The vendor report card
The bench’s primary output is not the ranking — it is what each harness would have to change to pass. Generated from the matrix:
| Harness | To pass, fix |
|---|---|
| Pi | naive-reader safe |
| OpenClaw | readable rationale |
| Claude Code | lean session · content-key share · dollar cost recorded · readable rationale · declares a format version · documented schema |
| Codex | lean session · no fixed-cost dumps · dollar cost recorded · declares a format version · documented schema · naive-reader safe |
| Kimi Code | lean session · content-key share · no fixed-cost dumps · dollar cost recorded · documented schema · naive-reader safe · self-contained |
| OpenCode | superseded share · thread structure · no schema break · declares a format version · live-tailable · documented schema · stable location |
| Hermes | no fixed-cost dumps · model attributable · thread structure · no schema break · declares a format version · live-tailable · stable location |
| Copilot CLI | lean session · no fixed-cost dumps · dollar cost recorded · thread structure · no schema break · declares a format version · stable location · self-contained |
| Antigravity | model attributable · token usage recorded · dollar cost recorded · thread structure · no schema break · declares a format version · documented schema · stable location · self-contained |
| Cursor Agent | per-event timestamps · model attributable · token usage recorded · dollar cost recorded · tool calls and outputs · readable rationale · declares a format version · standard-tools readable · live-tailable · documented schema · self-contained |
Hover an item for the evidence behind the fail. A vendor that fixes a gate flips it on the next re-score, and the change is recorded in the corrections log — the first harness to clear every scored gate gets named here.
Each area answers one question a developer actually has:
- Signal — is the log your work, or the harness’s paperwork?
- Completeness — can you audit what happened and what it cost?
- Stability — will your archive still parse after the next update?
- Openness — can you read your own history with tools you already have?
- Tooling — will scripts and history browsers survive its quirks?
The gate matrix
✓ pass · ✗ fail · — not run · ◦ unscored · · not applicable. Hover a cell for the evidence behind it. Underlined cells link to the checked source; their tooltip includes the source-check date. That date records a documentation check, not a new measurement or a score update. A source linked from a failing cell is the documentation checked, not proof that no other documentation exists.
| Gate | Pi | OClaw | Claude | Codex | Kimi | OCode | Hermes | Copilot | AntiG | Cursor |
|---|---|---|---|---|---|---|---|---|---|---|
| Signal | ||||||||||
| S1 — Lean session | ✓ | — | ✗ | ✗ | ✗ | — | — | ✗ | ✓ | ✓ |
| S2 — Content-key share | ✓ | ✓ | ✗ | ✓ | ✗ | ✓ | ✓ | ✓ | ✓ | ✓ |
| S3 — No fixed-cost dumps | ✓ | ✓ | ✓ | ✗ | ✗ | ✓ | ✗ | ✗ | ✓ | ✓ |
| S4 — Superseded share | — | — | — | — | — | ✗ | — | — | — | — |
| Completeness | ||||||||||
| C1 — Per-event timestamps | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ |
| C2 — Model attributable | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ | ✓ | ✗ | ✗ |
| C3 — Token usage recorded | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ | ✗ |
| C4 — Dollar cost recorded | ✓ | ✓ | ✗ | ✗ | ✗ | ✓ | ✓ | ✗ | ✗ | ✗ |
| C5 — Tool calls and outputs | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ |
| C6 — Readable rationale | ✓ | ✗ | ✗ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ |
| C7 — Thread structure | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ | ✗ | ✗ | ✗ | ✓ |
| Stability | ||||||||||
| T1 — No schema break | ✓ | ✓ | ✓ | ✓ | — | ✗ | ✗ | ✗ | ✗ | ✓ |
| T2 — Declares a format version | ✓ | ✓ | ✗ | ✗ | ✓ | ✗ | ✗ | ✗ | ✗ | ✗ |
| T3 — Honest version signal | ✓ | ✓ | · | · | ✓ | · | · | · | · | · |
| Openness | ||||||||||
| O1 — Standard-tools readable | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ |
| O2 — Live-tailable | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ | ✗ | ✓ | ✓ | ✗ |
| O3 — Documented schema | ✓ | ✓ | ✗ | ✗ | ✗ | ✗ | ✓ | ✓ | ✗ | ✗ |
| O4 — Stable location | ✓ | ✓ | ✓ | ✓ | ✓ | ✗ | ✗ | ✗ | ✗ | ✓ |
| Tooling | ||||||||||
| P1 — Naive-reader safe | ✗ | ✓ | ✓ | ✗ | ✗ | ✓ | ✓ | ✓ | ✓ | ✓ |
| P2 — Crash tolerant | ◦ | ◦ | ◦ | ◦ | ◦ | ◦ | ◦ | ◦ | ◦ | ◦ |
| P3 — Self-contained | ✓ | ✓ | ✓ | ✓ | ✗ | ✓ | ✓ | ✗ | ✗ | ✗ |
If you’re building on session files
For tool builders, auditors, and teams with retention or cost-analysis requirements — the properties that matter to a consumer of these records, These rows are generated from the matrix by the evaluator, so they can never disagree with it:
| You need | Qualifies today | Basis |
|---|---|---|
| Local cost auditing, in dollars | Pi, OpenClaw, OpenCode, Hermes | gate C4 |
| History you can grep and tail -f | Pi, OpenClaw, Claude Code, Codex, Kimi Code, Copilot CLI, Antigravity | gates O1+O2 |
| Readable reasoning or a stored summary | Pi, Codex, Kimi Code, OpenCode, Hermes, Copilot CLI, Antigravity | gate C6 |
| No format or layout change while we watched (windows vary per harness) | Pi, OpenClaw, Claude Code, Codex, Cursor Agent | gates T1+O4 |
Two editorial observations from the measurement work, decision-relevant but carrying no points: Hermes is the only store with built-in full-text search, and Codex keeps the most complete wire-replay record. And one caution from the gates: Cursor’s transcript is readable JSONL, but full reconstruction — model, timestamps, metadata — requires its opaque binary sidecar (gates O1, O2, P3).
The gates
-
S1 — Lean session (Signal): The identical one-line probe task adds ≤ 10 KB to the store (incremental bytes; database cold-start allocation is reported separately, not scored).
-
S2 — Content-key share (Signal): Strings under a published list of content-like keys (text, content, message, thinking, output, result, …) are ≥ 25% of stored bytes (corpus measurement). This heuristic captures real work product — messages, reasoning, tool output — but also counts bookkeeping stored under those keys, noted per-agent where known (Codex world_state, Copilot system prompt). Format-specific per-event classifiers are a 1.0 milestone.
-
S3 — No fixed-cost dumps (Signal): No single per-session bookkeeping record over 25 KB (system-prompt dumps, tool-catalog snapshots, context snapshots) in recent real sessions.
-
S4 — Superseded share (Signal): The share of stored bytes a final-state-lossless collapse would remove stays ≤ 20% on the real corpus; evidence names the rule per source and says what the collapse discards (added in v0.4 — S1-S3 cannot see superseded copies of live data under content keys). Final-state-lossless means every byte of final content survives and surviving events keep the timestamps C1 scores; only metadata on superseded copies (e.g. intermediate snapshot timestamps) may be lost, and the evidence must say so. A rule must hold for an ENTIRE source: OpenCode keep-newest-snapshot-per-message qualifies; Grok tool-call folding does not — its prefix property holds for only 66% of tool-call groups, so it is not even final-state-lossless there, and a collapse that must be re-proven per file is an audit, not a format property. Waste in stores outside the session store itself (tracing logs, upgrade snapshots) does not score this gate. Sources with no qualifying measured rule score not_run.
-
C1 — Per-event timestamps (Completeness): Every event carries a timestamp.
-
C2 — Model attributable (Completeness): The model behind every assistant message is recoverable from the record.
-
C3 — Token usage recorded (Completeness): Token counts are written locally.
-
C4 — Dollar cost recorded (Completeness): A dollar cost figure is written locally (premium-request counters do not pass).
-
C5 — Tool calls and outputs (Completeness): Both the tool invocation and its output are in the record.
-
C6 — Readable rationale (Completeness): A readable account of the model’s reasoning survives in the record — raw thinking or a stored summary beyond the final answer. Sealing may be deliberate vendor policy; the gate scores what the record contains, not the policy’s merits.
-
C7 — Thread structure (Completeness): Threads, branches, or subagent runs are recoverable via links or artifacts.
-
T1 — No schema break (Stability): No breaking schema change while under observation. Observation windows differ per harness (stated in each cell); a window too short to establish stability scores not_run.
-
T2 — Declares a format version (Stability): The artifact declares the version of its session FORMAT — a schema/protocol version an external reader can dispatch on. An application/CLI version stamped in the artifact does not pass: it identifies the writer, not the schema (tightened in v0.3; v0.2 wrongly accepted writer versions).
-
T3 — Honest version signal (Stability): The declared version matches the shipped reality. Scored only when T2 passes: with no version signal there is nothing to judge, and absence is already penalized by T2 (changed in v0.2 — v0.1 wrongly awarded this point to harnesses with no version at all).
-
O1 — Standard-tools readable (Openness): Readable at rest with a text editor or sqlite3; protobuf or hex-encoded payloads fail.
-
O2 — Live-tailable (Openness): One artifact you can tail -f holds the full running record.
-
O3 — Documented schema (Openness): The vendor publishes documentation for the session format.
-
O4 — Stable location (Openness): No wholesale storage-layout migration in the observation window.
-
P1 — Naive-reader safe (Tooling): A reader following the obvious structure gets every message exactly once.
-
P2 — Crash tolerant (Tooling): A truncated final write costs at most one record. UNSCORED in v0.2: asserted by format family only; needs a cross-harness truncation experiment (a 1.0 milestone).
-
P3 — Self-contained (Tooling): No sidecar file join is needed for title, cwd, or model.
Corrections
-
2026-08-23 — v0.3 → v0.4: S4 (superseded share) joins the Signal area, prompted by external disk-usage measurements. S1-S3 could not see the waste that actually fills disks: superseded copies of live data. OpenCode passes S1-S3 honestly, yet its event table stores a full message snapshot per streaming update — 17,940
message.updated.1rows for 4,639 distinct messages, 378 MB where keeping the newest per message is 16 MB (95.8% superseded). The redundant snapshots live under content keys (S2 counts them as work product) and each is under the S3 record cap, so the harness scored cleanly while filling disks. S4 scores the fraction of stored bytes a final-state-lossless collapse would remove, with a 20% limit, measured on the real corpus; the evidence names the rule per source and says what the collapse discards (for OpenCode: timestamps on superseded intermediate snapshots — surviving events keep theirs, so C1 is unaffected). A rule must hold for an entire source: Grok tool-call folding does not qualify, because its prefix property holds for only 66% of tool-call groups (one 8,359-event group looked pathological but carried genuine deltas from a render log), so a collapse there is a per-file audit, not a format property. Waste outside the session store itself does not score the gate: Codex’s unreclaimed SQLite freelist (470 MB of a 519 MB logs/tracing store, 90.6%, upstream openai/codex#35823) sits in a log database, not the rollout JSONL this bench scores, and onePRAGMA incremental_vacuumon the reader’s machine would change it with no vendor change — Codex scores not_run with that note, as does Hermes, whose one-shot pre-update snapshot (1,008 MB) holds credentials and is an upgrade artifact. Score and rank movement from this change: OpenCode 11/17 → 11/18 (64.7% → 61.1%), now tied with Kimi at rank 5 (Kimi moves 6 → 5); Codex and every other harness keep their percentage but gain an S4 not_run cell, which makes all ten ranks provisional — the † best/worst ranges treat an unmeasured S4 as a hypothetical pass or fail, so they widened for most harnesses (e.g. Hermes best case 5 → 3). Absence of a qualifying rule is still not leanness; the ranges are enumeration arithmetic, not evidence. Raw commands and reported values: receipts-2026-08-22-s4.md. -
2026-08-12 — O3 (documented schema) was originally scored fail for all ten harnesses. That was wrong. An external re-check found real vendor documentation that our search missed: Pi publishes a full session-format spec (in its tree since April 2026), OpenClaw documents its session store schema and transcript event structure, Hermes documents its persistence layers and stored fields, and Copilot documents its storage layout and persisted event types. Four cells flipped: Pi 17→18/19, OpenClaw 16→17/18, Copilot 11→12/19, Hermes 10→11/18. Kimi documents its session directory layout but not the wire-record schema, so its fail stands, as do Claude Code, Codex, Antigravity, and Cursor (nothing published) and OpenCode (table definitions in source, not documentation).
-
2026-08-12 (second correction, same review cycle) — v0.1 → v0.2. Codex was underscored by two gates: real rollouts carry plaintext
summary_texton ~35% of reasoning items (C6 passes — the gate accepts a stored summary) andparent_thread_id+sub_agent_activityrecords (C7 passes); Codex moves 12/19 → 14/19, tying Claude Code at rank 3. Antigravity’s P1 flips to pass — XML-wrapped content is awkward, not message loss. Two rubric fixes make this v0.2: T3 is now scored only when T2 passes (v0.1 wrongly awarded “honest version” points to harnesses with no version at all), and T1 states each harness’s actual observation window — Kimi’s ~10 days is too short to establish stability and is now not-run. Denominators shifted accordingly. -
2026-08-12 (third correction) — v0.2 → v0.3: T2 tightened to format versions only. v0.2 still awarded “declares a version” to harnesses that stamp an application/CLI version — the original defect restated. T2 now requires a schema/protocol version an external reader can dispatch on: Pi (
version1-3, documented), OpenClaw (version3), and Kimi (protocol_version) keep the point; Claude Code, Codex, Copilot, and OpenCode lose it (their stamps identify the writer, not the format), and their T3 becomes not-applicable. Claude and Codex 14→12/18, OpenCode 13→11/17, Copilot 12→10/18. The Codex C6/C7 evidence now cites a pinned artifact set with hashes (receipt).
Method
What this is, stated precisely: scores are mechanically generated from
published measurements and checklist verdicts; some underlying raw
artifacts (probe session files, corpus query transcripts) are not yet
public. A measurements manifest plus an evidence checklist feed
evaluate.py, which computes the Signal gates from fixed thresholds,
merges the checklist verdicts, and emits the data file this page renders;
measure.py recomputes per-artifact numbers from a session file.
Re-running the evaluator reproduces the scoring from the versioned inputs;
reproducing the observations end-to-end — harness execution to archived
raw artifacts to extraction — is the 1.0 milestone, and until it lands
this page does not claim to be a push-button-reproducible benchmark. The benchmark’s canonical home is
github.com/jazzyalex/session-bench
— methodology, data, evaluator, tests, and the public corrections
changelog. Agent Sessions temporarily hosts this Jekyll view using a
byte-identical, checked-in copy of Session-Bench’s generated
data/leaderboard.yml; it does not maintain a second evaluator or set of
inputs. To dispute a score, open an issue in the Session-Bench repository
with the measurement or evidence you contest, and re-run its evaluator.
The probe is one identical prompt — “List the files in the current directory, then say hello in one sentence.” — attempted through each harness’s CLI, headless/one-shot mode; where it produced a session, the artifact was measured byte-for-byte, and where it could not run, the affected gate says so. Desktop apps and IDE surfaces may use different stores; this bench scores the CLI session store only, and says so. Completeness, Openness, and Tooling verdicts are checklist items evaluated against real session files, the sanitized fixtures in the Agent Sessions repo, and the parsers that read all ten formats in production. Stability comes from a ledger that has fingerprinted each format’s schema roughly weekly since it entered monitoring — 2026-03-31 for the longest-observed harnesses, later for others (Cursor and OpenClaw from April, Pi from May, Kimi from late July); every stability verdict states its own window.
Grades can change, and the version scheme separates the two ways they can: the bench version (currently v0.4) is the rubric — gates, thresholds, scoring rules — and bumps only when a change breaks score comparability; the data date identifies a re-run under the same rubric. Formats drift — four of ten had a structural break in the last four months — and the bench re-scores when they do. v1.0 is reserved for end-to-end reproducibility: harness execution to archived artifacts to extraction, a tested crash gate, and per-event classifiers. Disputes and corrections are welcome as issues.